PaddlePaddle
PP-OCRv6
About
PP-OCRv6 is a 20M open-weight model from PaddlePaddle. PaddleOCR PP-OCRv6 medium text detection and recognition; scene OCR JSONL on image chat; text returns plain text; document_url fan-out via text. It accepts images and documents. Released June 11, 2026.
Parameters
20M
Published parameter count.
License
Apache-2.0
License on the weights.
Pricing
Token rates are US dollars per 1M tokens. Image rates are per 1K images. Audio rates are per 1M audio seconds.
| Rate | Price |
|---|---|
| Input / 1M | $0.02 |
| Cached input / 1M | $0.02 |
| Output / 1M | $0.40 |
Compare
PP-OCRv6 is the smallest of these OCR models, at 20M, and its published input rate is the lowest, $0.02 / 1M input.
| Model | What it does | Price | Parameters | Context |
|---|---|---|---|---|
| PP-OCRv6 | PaddleOCR PP-OCRv6 medium text detection and recognition; scene OCR JSONL on image chat; text returns plain text; document_url fan-out via text. | $0.02 / 1M input | 20M | — |
| PaddleOCR-VL 1.6 | PaddleOCR-VL-1.6 for OCR, tables, formulas, and charts. | $0.15 / 1M input | 0.9B | 16K |
| DeepSeek-OCR-2 | DeepSeek OCR 2 and markdown extraction. | $0.25 / 1M input | 3.4B | 32K |
| dots.mocr | Multilingual document layout parsing and markdown OCR. | $0.20 / 1M input | 3B | 32K |
Benchmarks
Published scores for PP-OCRv6, from the PP-OCRv6 paper. Medium tier.
- Detection Hmean86.2
| Reading | Example |
|---|---|
| Qualitative | Clear structure, grounded in the input |
| Quantitative | Detection Hmean: 86.2. |
| Cost and performance | Lower listed rate, mid-pack latency |
Performance
Latency is the end-to-end round trip. Throughput is completion tokens divided by that time. It is a request rate, not decode speed.
Latency
139 ms
Throughput
536 tok/s
Requests
7,678
Examples
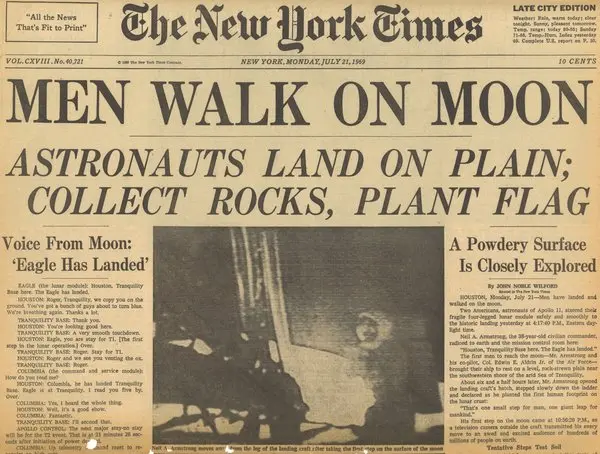
Scene-text OCR
PP-OCRv6 reads a New York Times newsstand in 120 ms.
{"lines":[{"text":"The New York Times","score":0.99,"box_xyxy":[..]}, ...]}
Supported inputs
- textNo
A request with no media part is a
400. - image_urlYes
One per request. A second
image_urlpart is a400. - video_urlNo
Not accepted.
- document_urlYes
One PDF, up to 128 pages, rasterized per page at
document_dpi(default 96). See Document Inputs.
- Default method
ocr. - Alias:
pp-ocrv6.
Methods
Methods this model serves. Payload shapes are in the docs.
| Method | Returns |
|---|---|
| ocr | Region items with bbox_xywh, optional poly_xy, text, score |
| detect | Region items with bbox_xywh and optional poly_xy, geometry only |
| text | Recognized text stitched in reading order |
The payload kind is the same for an image and for each page of a PDF. Text mode emits the payload alone for one image, and one <document> / <page> block for a PDF. In JSON mode an image content is the tagged container above, and a document page content is always doc.page.blocks. See Methods & Response Format.
Coordinates are normalized 0-1 against the image or rasterized page, at precision decimals (default 4). text is plain scene text stitched in reading order, not generative Markdown.
Method parameters
| Parameter | Default | Description |
|---|---|---|
lang | en | Recognition language (en, ch, japan, ...), on every method. |
score_threshold | 0.5 | ocr and text: drop text regions below this recognition confidence (0.0-1.0). detect returns every region. |
Estimate cost
Estimate. A page is 2,500 input tokens and 1,000 output tokens.
$0.45
Quick start
Call this model on the OpenAI-compatible gateway. The model id is already filled in.
Response
A single image returns the region container alone, with no wrapper:
{"object": "doc.ocr.lines", "items": [{"bbox_xywh": [0.0332, 0.0138, 0.1719, 0.0331], "poly_xy": [[0.0332, 0.0138], [0.2051, 0.0138], [0.2051, 0.047], [0.0332, 0.047]], "text": "Invoice", "score": 0.998}, {"bbox_xywh": [0.0332, 0.0829, 0.2598, 0.0331], "text": "Total: $99.00", "score": 0.987}]}
For PDFs, each page's content is doc.page.blocks, and every region becomes one block with the same geometry under a zero-based block_id. See the Document OCR guide.