Alibaba
Qwen3.5 0.8B
About
Qwen3.5 0.8B is a 0.8B open-weight model from Alibaba. Multimodal chat model with up to 64 images or one video per request. It accepts text, images, and video. Context window is 256K. Released February 28, 2026.
Parameters
0.8B
Published parameter count.
Context window
256K
Tokens of context on a request.
License
Apache-2.0
License on the weights.
Pricing
Token rates are US dollars per 1M tokens. Image rates are per 1K images. Audio rates are per 1M audio seconds.
| Rate | Price |
|---|---|
| Input / 1M | $0.08 |
| Cached input / 1M | $0.02 |
| Output / 1M | $0.15 |
Compare
Qwen3.5 0.8B is the smallest of these chat models, at 0.8B, and its published input rate is the lowest, $0.08 / 1M input.
| Model | What it does | Price | Parameters | Context |
|---|---|---|---|---|
| Qwen3.5 0.8B | Multimodal chat model with up to 64 images or one video per request. | $0.08 / 1M input | 0.8B | 256K |
| Qwen3.8 27B | Reasoning VLM (image + video + text) | $0.35 / 1M input | 27B | 164K |
| Gemini 3.5 Flash Lite | Fastest and cheapest Gemini tier. Multimodal chat; emits no reasoning tokens. | $0.30 / 1M input | — | 1M |
| Gemini 3.7 Flash | Newest Gemini Flash tier with extended reasoning. Multimodal chat + native video. | $0.75 / 1M input | — | 1M |
Benchmarks
Published scores for Qwen3.5 0.8B, from the Qwen3.5-0.8B model card. Thinking-mode scores.
- MMMU49
- RealWorldQA63.4
| Reading | Example |
|---|---|
| Qualitative | Clear structure, grounded in the input |
| Quantitative | MMMU: 49. |
| Cost and performance | Lower listed rate, mid-pack latency |
Performance
Latency is the end-to-end round trip. Throughput is completion tokens divided by that time. It is a request rate, not decode speed.
Latency
40 ms
Throughput
633 tok/s
Requests
1,493
Examples
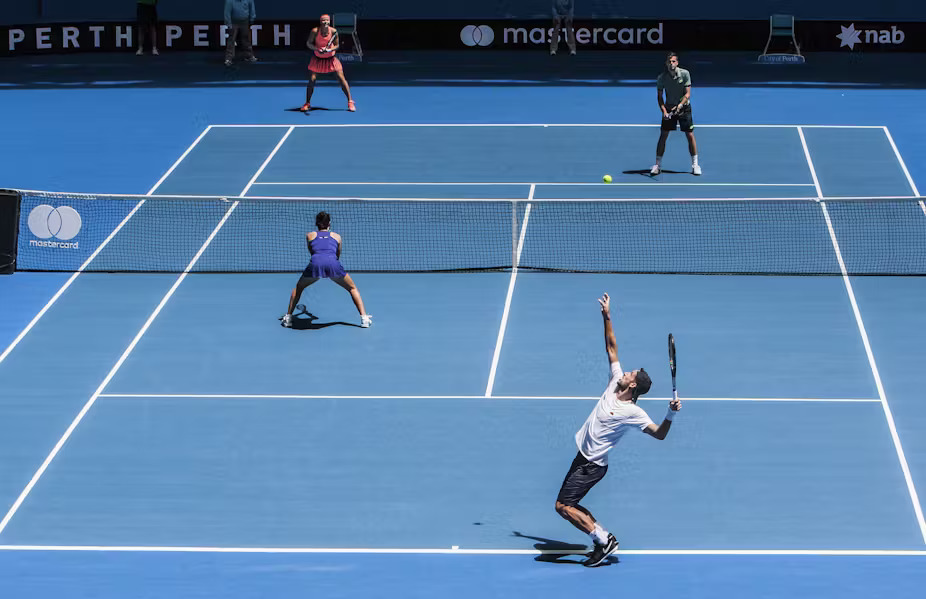
Counting tennis balls
Qwen3-VL 0.8B answers a counting question on a court photo.
{"answer":"4"}
Supported inputs
- textYes
Text-only prompts are accepted.
- image_urlYes
Up to 64 per request, read together as one prompt. See Image Inputs.
- video_urlYes
One clip. Tune sampling with
video_fps,video_max_frames, andvideo_resolutionat the top level. See Video Inputs. - document_urlNo
A
document_urlpart is a400capability error. Use an OCR model such aspaddleocr/pp-ocrv6for PDFs.
- Default and only method: free-form
chat(nomethodormethod_params).response_format={"type":"json_schema"}is supported. - Context window 262,144 tokens (256K).
- The larger
qwen/qwen3.8-27bshares the same contract. - Weights:
Qwen/Qwen3.5-0.8B.
Methods
Methods this model serves. Payload shapes are in the docs.
| Method | Returns |
|---|---|
| chat (default) | The model's reply, verbatim |
A chat VLM is pass-through. Text mode returns the reply with no wrapper, even with several images: the model reads them together and produces one reply. JSON mode returns the model's own JSON, with no data envelope. See Methods & Response Format.
Estimate cost
Estimate. An hour of video is 15 frames a minute at 256 tokens a frame, plus the audio in that request, and 500 output tokens a minute.
$32.15
Quick start
Call this model on the OpenAI-compatible gateway. The model id is already filled in.
Response
A silver sedan is parked on a sunlit street beside a row of trees.
For video, pass a video_url part and tune sampling with video_fps / video_max_frames. See Video Inputs.